SuperDataSet
SuperDataSet is responsible for loading your data and configuring it for a training/evaluation experiment. We support a range of file formats and configuration options.
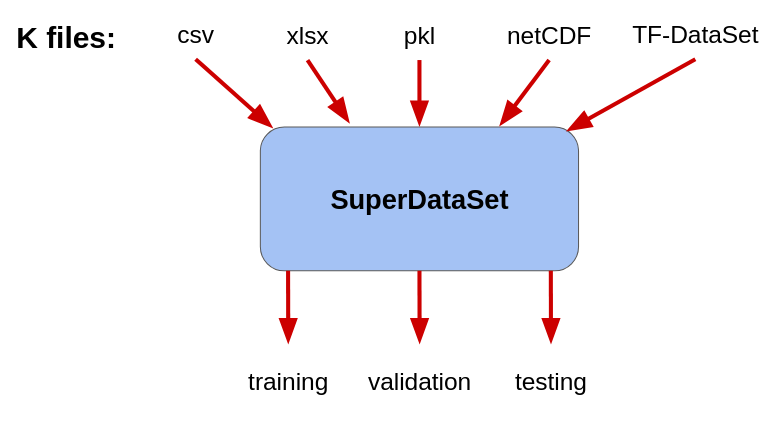
Data Sets
A data set for machine learning is composed of a set of examples. Often, a single example is composed of an input/desired output pair, meaning that for a given numerical input, the ideal model will produce the desired output. For any machine learning experiment, it is important to distinguish between several different data set types:
-
Training data sets are used to adjust the parameters of a model. In the deep network context, these parameters are adjusted incrementally to gradually reduce the prediction errors made by the model on the training data set.
- Validation data sets are independent of the training set and are used to:
- Evaluate the performance of a model at each training step. This information is often used to detech when training is complete.
- Compare the model to itself under different choices of hyper-parameter sets.
- Test data sets are independent of both the training and validation data sets, and act as a simulation of possible future data sets. As such, a test data set is used only for the final evaluation of a model after hyper-parameter choices are made.
Stochastic Nature of Machine Learning Training and Evaluation
The training of machine-learned models is a stochastic process due to a range of factors, including:
- the selection of the data used for training, validatin, and testing,
- the initial choices for the model parameters (which are randomly selected), and
- random factors during the training process (e.g., random assignment of examples to training batches, or Dropout).
The consequence of these random processes is that when we train a model multiple times (even when we think the conditions are the same), the performance of the model (e.g., accuracy) can vary to some degree. Using statistical language, we say that the performance is a random variable. In practice, this means that training and evaluating a model cannot be done just once - if we want to show that a model is doing its job and doing it well, then we must show that it does so consistently under different training and evaluation conditions.
SuperDataSet provides support for a range of different ways of constructing data sets, depending on what your goals are - all the way from only using a training set for a quick, informal exaperiment, to assembling multiple training, validation, and testing data sets to be used for formal evalution, including Cross-Validation.
SuperDataSet Topics
- Example: Loading Data Files
- Supported File Types
- Intermediate: Data Files to Data Sets
- Advanced: Internal Data Representation