Data Files to Data Sets
The translation from the contents of a set of files to the training/validation/testing data sets is handled as a multi-step process, with two intermediate representations.
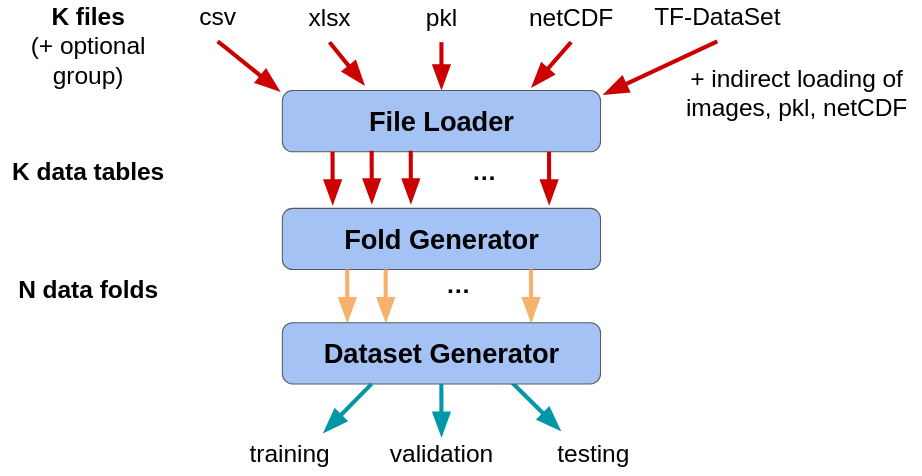
The translation process is as follows:
- File Loader: Each data file is loaded into a single data table. Each table consists of multiple data examples.
- Supports a range of different file formats
- Each example includes one or more inputs, one or more outputs, (optional) example weight, and (optional) example group
- File Loader Details
- Fold Generator: the examples contained within the data tables are sorted into one or more data folds.
- The sorting process can be done table-by-table or example-by-example
- Fold Generator Details
-
Dataset Generator: Assembles training/validation/testing data sets by combining non-overlapping data folds. Specifically:
-
The training set is one or more folds
-
The validation set is zero or more folds
-
The testing set is zero or one fold
-